> This page is for version dev.
> For other versions, use one of these documentation indexes:
> - Latest (v1.5.1) (default): https://docs.nvidia.com/dynamo/latest/llms.txt
> - dev: https://docs.nvidia.com/dynamo/dev/llms.txt
> - v1.5.1: https://docs.nvidia.com/dynamo/v1.5.1/llms.txt
> - v1.5.0: https://docs.nvidia.com/dynamo/v1.5.0/llms.txt
> - v1.4.2: https://docs.nvidia.com/dynamo/v1.4.2/llms.txt
> - v1.4.1: https://docs.nvidia.com/dynamo/v1.4.1/llms.txt
> - v1.4.0: https://docs.nvidia.com/dynamo/v1.4.0/llms.txt
> - v1.3.0: https://docs.nvidia.com/dynamo/v1.3.0/llms.txt
> - v1.2.1: https://docs.nvidia.com/dynamo/v1.2.1/llms.txt
> - v1.2.0: https://docs.nvidia.com/dynamo/v1.2.0/llms.txt
> - v1.1.1: https://docs.nvidia.com/dynamo/v1.1.1/llms.txt
> - v1.1.0: https://docs.nvidia.com/dynamo/v1.1.0/llms.txt
> - v1.0.2: https://docs.nvidia.com/dynamo/v1.0.2/llms.txt
> - v1.0.1: https://docs.nvidia.com/dynamo/v1.0.1/llms.txt
> - v1.0.0: https://docs.nvidia.com/dynamo/v1.0.0/llms.txt
> - v0.9.1: https://docs.nvidia.com/dynamo/v-0-9-1/llms.txt
> - v0.9.0: https://docs.nvidia.com/dynamo/v-0-9-0/llms.txt
> - v0.8.1: https://docs.nvidia.com/dynamo/v-0-8-1/llms.txt
> - v0.8.0: https://docs.nvidia.com/dynamo/v-0-8-0/llms.txt
> - v0.7.1: https://docs.nvidia.com/dynamo/v-0-7-1/llms.txt
> - v0.7.0: https://docs.nvidia.com/dynamo/v-0-7-0/llms.txt
> For clean Markdown content of this page, append .md to this URL. For the complete documentation index, see https://docs.nvidia.com/dynamo/llms.txt. For full content including API reference and SDK examples, see https://docs.nvidia.com/dynamo/llms-full.txt.
# vLLM Sidecar
**Experimental.** The sidecars and their deployment examples are
experimental. Manifests, flags, and behavior may change without notice.
`dynamo-vllm-sidecar` connects a Dynamo worker to vLLM's native gRPC server
(`vllm-rs`). See [Sidecar Backends](/dynamo/dev/knowledge-base/concepts/system-architecture/sidecar-backends)
for the architecture.
For the best and latest support, use the upstream vLLM nightly image,
which carries the latest gRPC server updates: [`vllm/vllm-openai:nightly`](https://hub.docker.com/r/vllm/vllm-openai/tags?name=nightly).
## Support Matrix
| Feature | Supported |
|---|---|
| Aggregated | Yes |
| Disaggregated | Yes |
| KV routing | Yes |
## Launch Locally
See [`lib/sidecar/vllm/launch/`](https://github.com/ai-dynamo/dynamo/tree/main/lib/sidecar/vllm/launch)
for all topologies. For example, aggregated serving on one GPU:
```bash
export DYN_DISCOVERY_BACKEND=file # single host: no etcd or NATS needed
./lib/sidecar/vllm/launch/agg.sh
```
In a second terminal:
```bash
curl -s localhost:8000/v1/chat/completions \
-H 'Content-Type: application/json' \
-d '{"model":"Qwen/Qwen3-0.6B","messages":[{"role":"user","content":"Hello"}],"max_tokens":32}'
```
## Deploy on Kubernetes
See [`lib/sidecar/vllm/deploy/`](https://github.com/ai-dynamo/dynamo/tree/main/lib/sidecar/vllm/deploy)
for all manifests. For example, aggregated serving:
Before applying, replace `/dynamo-sidecar` in the manifest with a
[sidecar image](/dynamo/dev/knowledge-base/concepts/system-architecture/sidecar-backends#container-packaging).
```bash
kubectl apply -f lib/sidecar/vllm/deploy/agg.yaml -n
kubectl port-forward -n svc/vllm-sidecar-agg-frontend 8000:8000
```
## Topologies
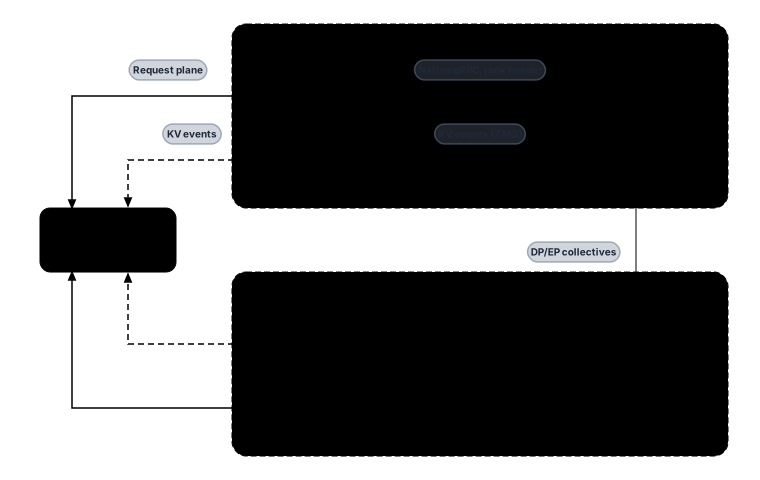
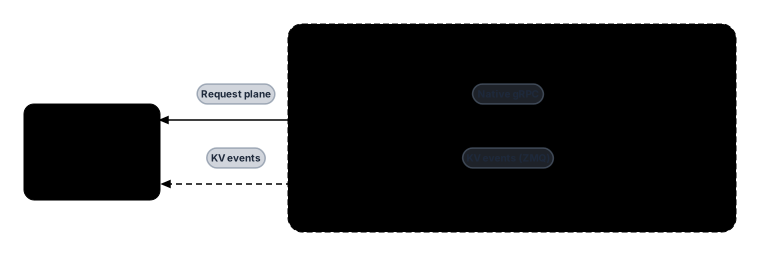
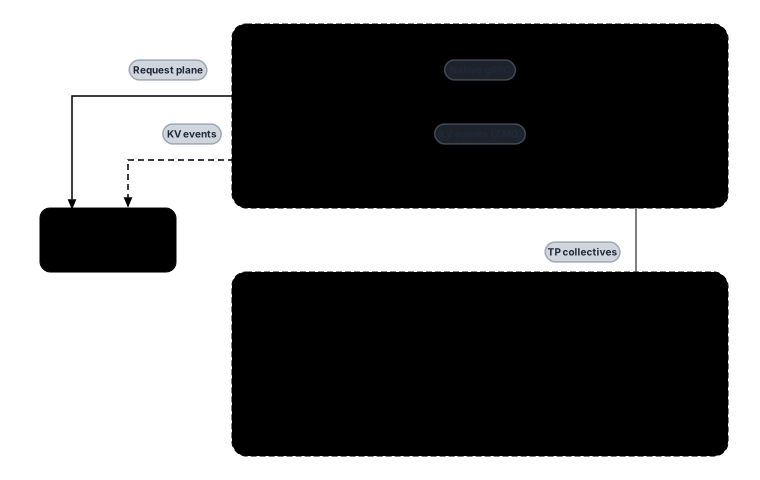
The frontend reaches each sidecar over Dynamo's request, discovery, and event
planes; the sidecar reaches the engine over its native gRPC API. Dashed arrows
carry KV events.
### Single-Node TP
One engine on one node, with one sidecar.
### Multi-Node TP
One engine spans two nodes. Only the leader node has a sidecar; the follower
node holds the remaining TP ranks.
### Multi-Node DP
Hybrid DP load balancing: each node runs vLLM for its local DP ranks plus a
sidecar that serves requests. The frontend routes to either node.